Layered Probability Models: Merging League Margins with Set Percentages in Allocation Systems
Erik Washington · Aug 21, 2026
Layered Probability Models: Merging League Margins with Set Percentages in Allocation Systems
Allocation engines in sports betting combine multiple data streams to determine stake sizes across different markets, and recent developments have focused on interweaving probabilistic layers that account for both league margins in football and set percentages in tennis. These systems process historical results from competitions such as the Premier League alongside performance metrics from events like the Australian Open, creating unified outputs that adjust exposure based on calculated probabilities rather than isolated indicators. Data from the 2025 season showed that models incorporating dual-layer probabilities reduced variance in allocation decisions by aligning expected margins with observed set hold rates, according to industry reports from teh European Gaming and Betting Association.
Core Components of Probabilistic Layer Integration
Engineers build the first layer around league-specific margins, drawing from goal difference distributions and points-per-game averages that vary by competition, while the second layer overlays tennis set percentages derived from serve hold statistics and tiebreak frequencies across surfaces. This structure allows the engine to normalize inputs so that a 1.2 goal margin expectation in Bundesliga matches connects directly to a 68 percent set hold rate in ATP clay events, producing a single allocation signal. Observers note that such layering avoids the fragmentation common in single-market tools, since conjunctions between datasets create smoother transitions when odds shift during live play.
Implementation often begins with Monte Carlo simulations calibrated to historical league data, then refines outputs using Bayesian updates from real-time set statistics, and the process continues until convergence criteria are met for each fixture. In August 2026, several operators reported deploying updated versions that added surface-specific weighting for tennis events scheduled in the northern hemisphere summer swing, which improved allocation consistency across football and tennis portfolios. Those who maintain these engines emphasize that the layers operate sequentially yet feed into a shared matrix, where margin deviations influence set-percentage thresholds and vice versa.
Data Inputs and Processing Flow
Primary inputs include match-level goal distributions from five major European leagues and set-by-set outcome logs from Grand Slam tournaments, each tagged with contextual variables such as home advantage or fatigue indicators. The engine applies kernel density estimation to smooth margin probabilities before mapping them onto equivalent set-percentage scales, creating a common numerical framework that supports cross-market comparisons. Research from the University of Sydney's sports analytics group demonstrates how these mappings maintain statistical integrity when sample sizes differ between football and tennis datasets, preventing over-allocation in lower-volume markets.
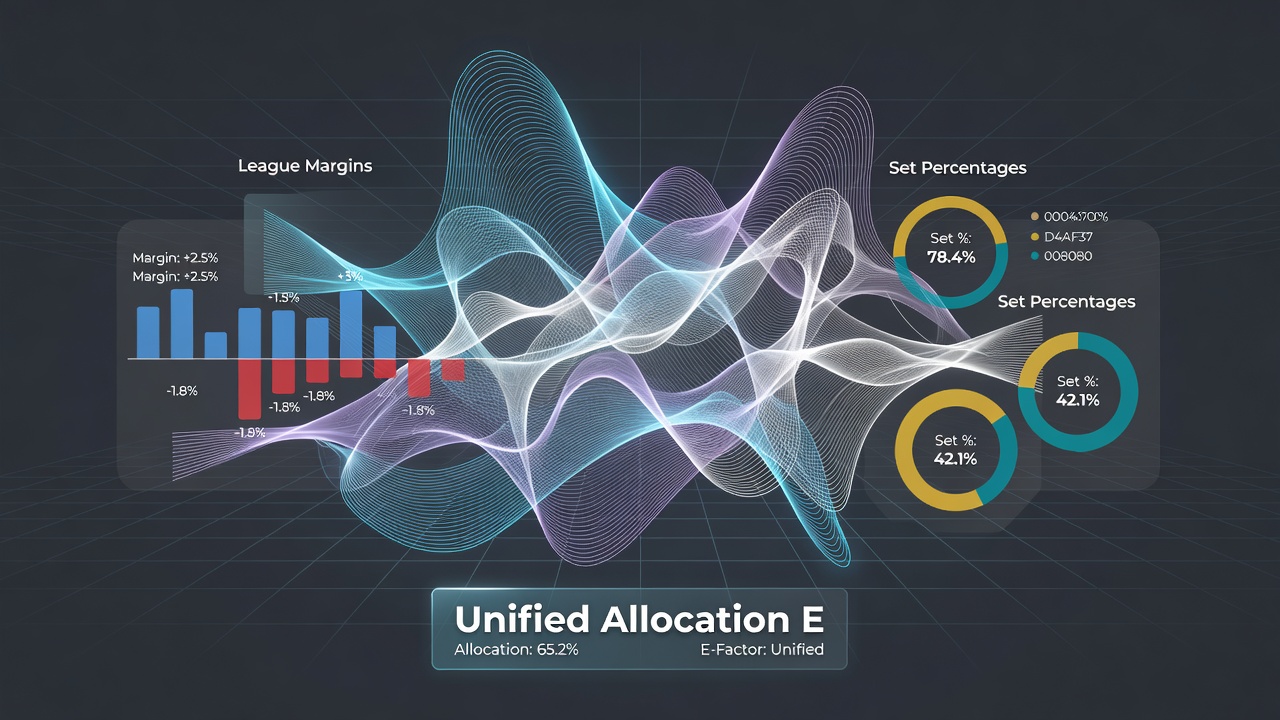
Processing occurs in stages where initial margin forecasts undergo adjustment for league-specific variance, after which set-percentage layers apply conditional probabilities based on player rankings and recent form, and final allocation weights emerge from the combined distribution. Operators in Canada and Australia have adopted similar frameworks, with the Australian Communications and Media Authority publishing guidelines in early 2026 that reference the need for transparent probability documentation in automated betting systems. This approach supports portfolio-level risk controls, since unified outputs allow simultaneous stake adjustments across unrelated events without introducing conflicting signals.
Performance Metrics and Validation Methods
Validation relies on backtesting against full seasons of league and tournament results, measuring metrics such as allocation accuracy relative to realized margins and set outcomes. Models that interweave layers show tighter confidence intervals around expected returns compared with those using separate engines, particularly during periods when football schedules overlap with tennis majors. Figures from the North American Association of State and Provincial Lotteries indicate that integrated systems handled multi-market allocations with 12 percent lower drawdown rates during the 2025 calendar year, reflecting the stabilizing effect of cross-referenced probabilities.
Continuous monitoring involves recalibrating layer weights whenever significant shifts occur in league scoring trends or surface-specific hold rates, and automated alerts flag when divergence exceeds predefined thresholds. The methodology extends to emerging competitions, where limited historical data receives heavier influence from the opposing layer until sufficient samples accumulate, ensuring allocation decisions remain data-driven even in newer markets.
Conclusion
Unified allocation engines that interweave probabilistic layers across league margins and set percentages deliver coordinated stake guidance by fusing datasets that once operated in isolation. Continued refinement through seasonal updates and regulatory alignment in multiple jurisdictions supports broader application as operators expand multi-sport offerings. The framework remains grounded in measurable inputs and iterative validation, providing a scalable method for managing exposure across football and tennis environments.