Interconnected Modeling Approaches for Uncovering Inefficiencies Across Football and Tennis Betting Markets
Theo Powell · Jul 22, 2026
Interconnected Modeling Approaches for Uncovering Inefficiencies Across Football and Tennis Betting Markets
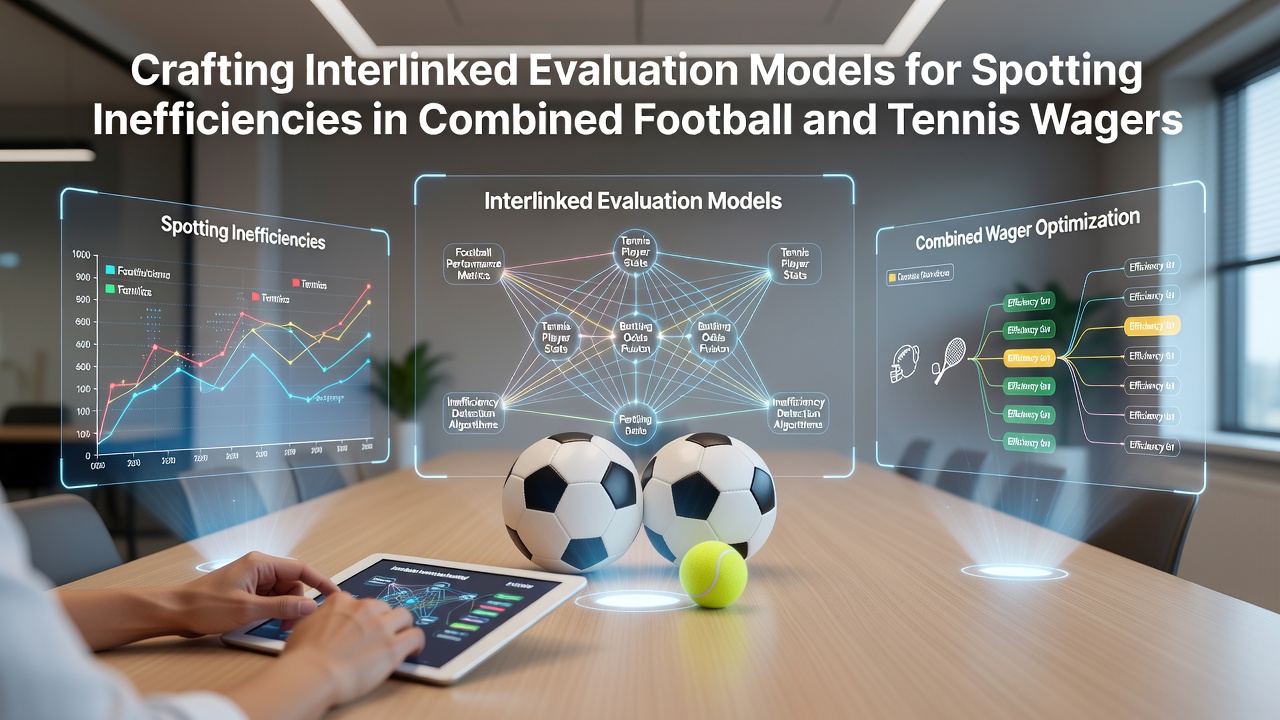
Analysts in the sports betting sector have turned toward interconnected evaluation models that combine datasets from football and tennis to locate pricing discrepancies in multi-sport wagers, and these frameworks rely on shared variables such as player fatigue indicators, weather influences, and historical head-to-head records that span both disciplines. Researchers construct these systems by first gathering granular statistics from premier league fixtures and grand slam tournaments then mapping correlations between goal-scoring rates and serve-hold percentages to reveal where bookmakers have misaligned odds on combined selections.
Core Components of Linked Assessment Frameworks
Each model begins with data ingestion layers that pull live scores, betting lines, and performance metrics from multiple providers, while subsequent processing stages apply regression techniques to isolate inefficiencies that emerge when football and tennis outcomes interact within a single wager. Observers note that these stages often incorporate Monte Carlo simulations calibrated on past seasons, allowing the system to test thousands of scenario combinations and flag instances where implied probabilities diverge from computed likelihoods. Data shows that such divergences appear most frequently during overlapping tournament schedules when player rest periods become constrained across both sports.
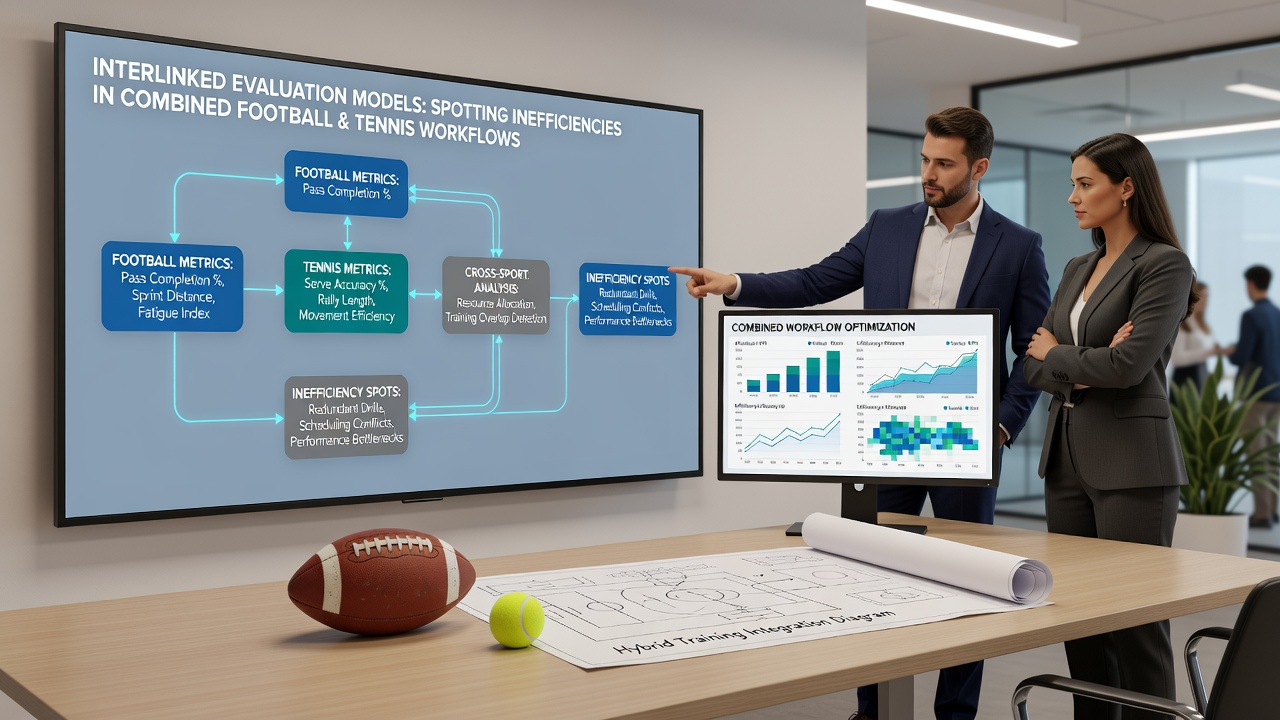
Modular design allows separate sub-models for football-specific factors like expected goals and tennis-specific metrics such as first-serve percentage to exchange outputs through standardized interfaces, and this interchangeability supports rapid updates when new match data arrives. Experts have observed that July 2026 brought expanded access to unified APIs from European and North American data vendors, which in turn accelerated the integration of cross-sport variables into existing evaluation pipelines.
Data Integration and Variable Selection
Selection of input variables requires careful alignment so that factors relevant to one sport enhance rather than dilute signals from the other, and practitioners typically begin with a core set that includes travel distance, surface type transitions, and injury recovery timelines shared across football squads and tennis players. Studies from academic institutions indicate that adding contextual elements such as crowd density at venues and broadcast scheduling patterns further refines model accuracy for combined wagers. One documented case involved a European research team that linked defensive metrics from Bundesliga matches with baseline return statistics from ATP events, uncovering consistent underpricing on accumulator bets that paired underdog football results with favored tennis holds.
Validation Techniques and Performance Tracking
Validation proceeds through backtesting against archived odds and outcomes, with performance measured by metrics that include return on investment and hit rate across stratified wager types. Analysts apply cross-validation methods that reserve portions of historical data for out-of-sample testing, thereby reducing the risk of overfitting to specific seasons or player cohorts. Reports from industry research groups such as the Australian Gambling Research Centre highlight how these validation routines have identified persistent inefficiencies in mixed-sport parlays during periods of concurrent major events.
Real-time monitoring components track model outputs against live market movements, triggering alerts when discrepancies exceed predefined thresholds, and this capability proves especially useful during condensed calendars where football midweek fixtures overlap with tennis qualifying rounds. Figures from the Nevada Gaming Control Board quarterly summaries reveal steady growth in reported handle on multi-sport products, underscoring the commercial relevance of refined detection methods.
Implementation Challenges and Mitigation Strategies
Implementation faces hurdles related to data latency and format inconsistencies between football and tennis sources, yet teams address these through standardized transformation pipelines that normalize timestamps and unit measurements. Computational demands rise when models expand to include additional variables, prompting the adoption of cloud-based processing clusters that scale during peak tournament windows. Those who have deployed such systems report that regular recalibration against fresh results maintains predictive power even as betting markets evolve in response to new information flows.
Conclusion
Interconnected evaluation models continue to evolve as data sources multiply and computational tools advance, providing structured methods for identifying pricing gaps in combined football and tennis wagers. Continued refinement of these frameworks depends on sustained collaboration between data scientists, statisticians, and market observers who supply domain-specific insights that keep the models grounded in observable patterns.